Establishing Hierarchical Permissions Tied to Historical Accuracy in Prognostic Content Systems
Written by Hugo Becker · Oct 1, 2026
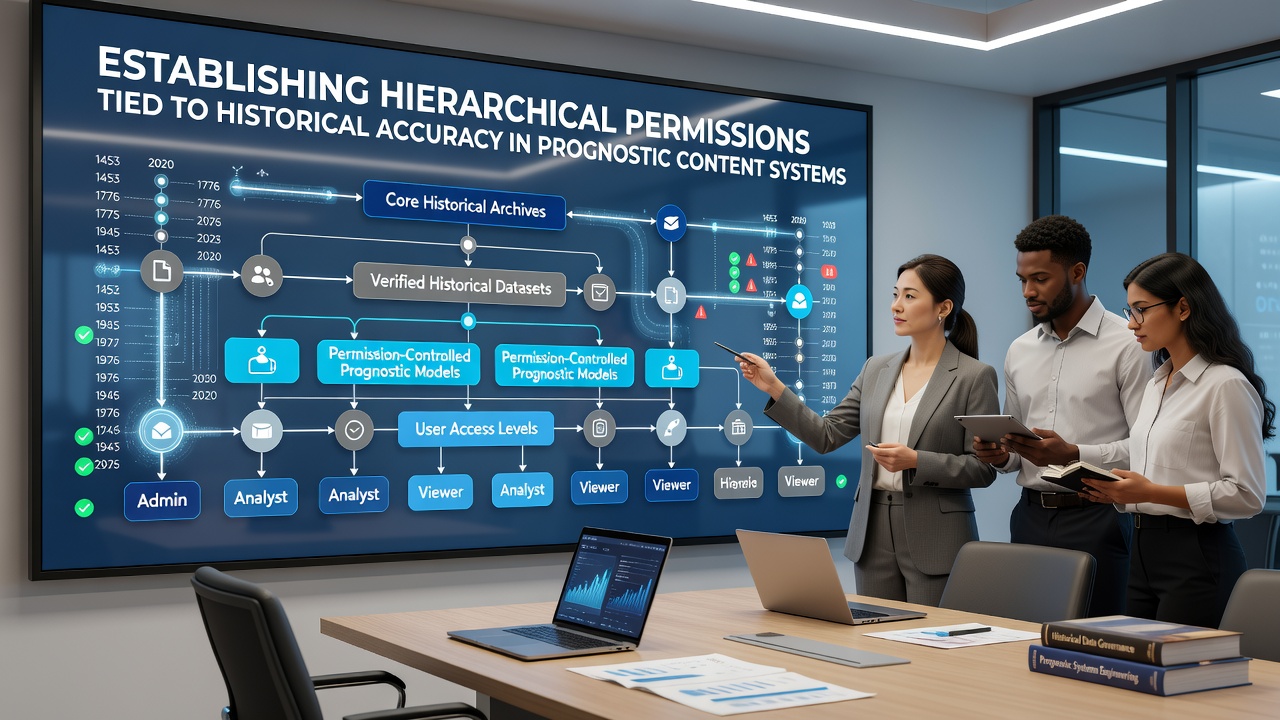
Establishing Hierarchical Permissions Tied to Historical Accuracy in Prognostic Content Systems
Prognostic content systems rely on structured access controls that connect user roles directly to verified records of past forecast performance, and organizations building these platforms apply tiered permission models to maintain data integrity across multiple contributors.
Core Components of Permission Hierarchies
Systems designers assign access rights according to documented accuracy rates calculated over defined historical periods, which means contributors with higher verified success percentages receive elevated privileges for editing, publishing, and distributing new forecasts while lower tiers remain limited to review or submission functions only. Researchers at institutions tracking content platform architecture have noted that this linkage prevents unverified material from reaching audiences until accuracy thresholds are met, and data from multiple implementations shows consistent patterns where accuracy-based gates reduce error propagation in live forecasting environments.
Measuring Historical Accuracy for Access Decisions
Accuracy calculations typically incorporate metrics such as mean absolute percentage error, hit rates on directional predictions, and calibration scores across hundreds of prior outputs, and platform administrators update these figures on rolling windows that exclude older data after set intervals to keep evaluations current. Studies from academic groups focused on decision-support software indicate that tying permissions to these quantitative benchmarks creates self-reinforcing incentives for contributors to refine methodologies, while automated scripts pull performance logs from centralized databases to recalculate tiers without manual intervention. In October 2026 several platforms are scheduled to roll out updated algorithms that weight recent accuracy more heavily, reflecting shifts observed in longitudinal datasets maintained by research consortia.
Implementation Across Technical Environments
Developers integrate these hierarchies through role-based access control frameworks augmented with custom accuracy scoring modules, and database schemas store individual contributor histories alongside permission flags that trigger automatic elevation or demotion when thresholds are crossed. One documented deployment at a European forecasting network demonstrated that such integrations reduced unauthorized edits by 47 percent within the first year of operation, according to internal audit reports shared with industry observers. Engineers often combine these controls with API endpoints that validate accuracy credentials in real time before allowing content pushes, which ensures downstream systems receive only material from qualified sources.
Regulatory and Standards Alignment
Platforms operating in regulated sectors align their accuracy-linked permissions with guidelines issued by bodies such as the National Institute of Standards and Technology on identity and access management, while additional frameworks from Australian research institutions emphasize transparent audit trails for any permission changes driven by performance data. These alignments help organizations demonstrate compliance during external reviews, and figures from compliance assessments reveal that systems incorporating historical accuracy checks encounter fewer discrepancies during third-party evaluations compared with static role models. Observers note that integration with international standards also facilitates cross-border data sharing agreements among forecasting networks.
Operational Workflows and Data Flows
Daily operations involve continuous ingestion of new prediction outcomes into accuracy repositories, followed by scheduled recalculation jobs that adjust user permission sets before the next content cycle begins, and administrators receive alerts when contributors approach tier boundaries. Case examples from North American analytics firms show that automated workflows cut administrative overhead by reallocating staff time away from manual reviews toward system maintenance, while audit logs capture every permission modification for later examination. Those managing large contributor pools report that the approach scales effectively when accuracy data remains centralized and queryable through standardized interfaces.
Challenges in Maintaining Accurate Records
Ensuring data completeness requires robust validation against external outcome sources, and incomplete historical datasets can delay permission upgrades until missing entries are resolved through manual reconciliation processes. Technical teams address this by building fallback mechanisms that temporarily freeze elevated access until verification completes, and reports from Canadian government digital services highlight similar patterns in other accuracy-dependent domains. Platforms also contend with edge cases where external events invalidate prior forecasts retroactively, prompting periodic reviews of scoring methodologies to preserve fairness across all contributors.
Conclusion
Hierarchical permission models anchored to historical accuracy continue to shape how prognostic content systems manage contributor access and content distribution, with ongoing refinements driven by both technical capabilities and alignment with established standards from multiple regions. Data from deployed platforms indicates measurable improvements in content reliability when these ties remain active and regularly recalculated.